ETCD Raft Consensus
How does Kubernetes keep its single source of truth safe when a machine can fail? ETCD runs a small group of replicas that agree on every write through the Raft protocol: one Leader takes the change, copies it to the Followers, and commits only once a majority has stored it. That quorum rule is what lets a cluster of three lose a Node and still never serve a half-written state. Lose the majority and it stops writing until quorum returns.
Play the animation 6 steps, animated, best on a wide screen
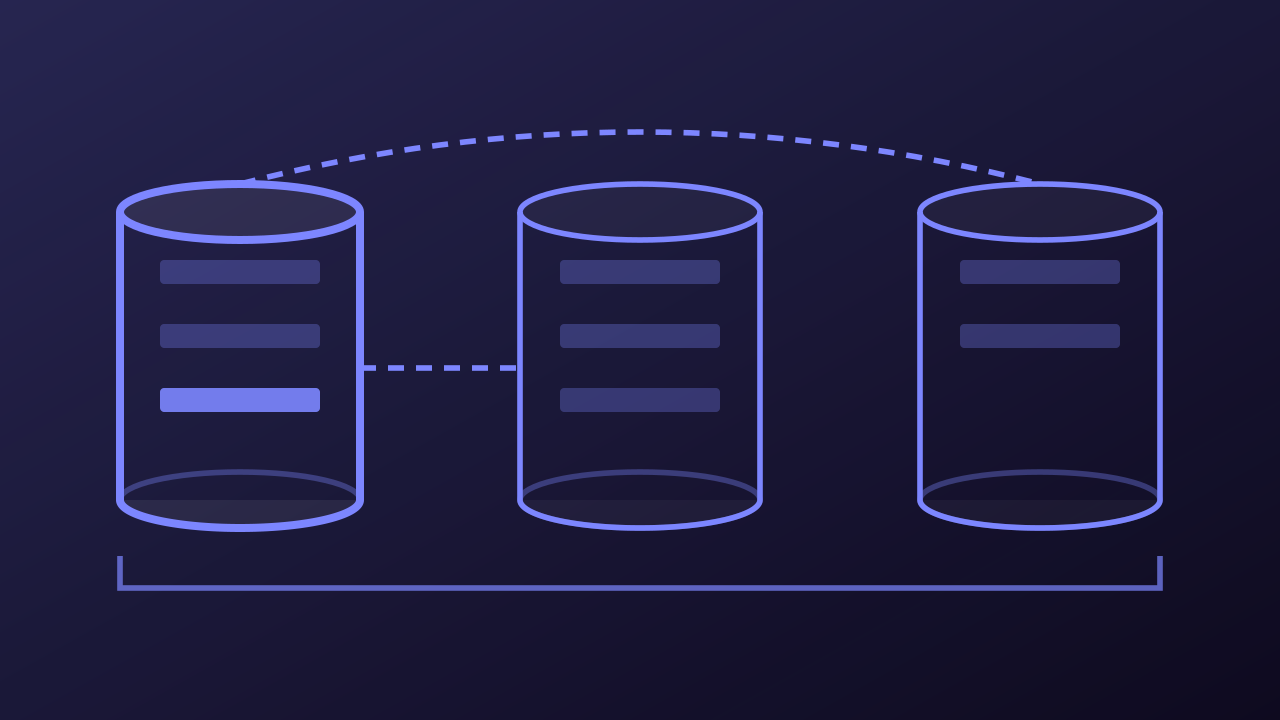
ETCD Raft Consensus, step by step
-
The API issues a write for a new Pod, and it should be the only component reaching ETCD at all. Every write goes through the Leader, the single point that orders all changes. A write that lands on a Follower is forwarded to the Leader, and a linearizable read waits for the Leader to confirm it still holds a quorum, so no read sees a split view.
Play from step 1 -
The Leader appends the write as entry 9 in its own log, right after the 8 entries already stored. For now the entry lives on a single replica and stays uncommitted, so commitIndex is still 8 and the new Pod is invisible to readers. Nothing becomes durable until a majority holds it, and the Leader counts as one.
Play from step 2 -
The Leader sends an AppendEntries RPC carrying entry 9 to both Followers at once. Each Follower rejects a stale term and checks that its entry 8 has the term the Leader sent for it before accepting, which is what keeps the replicas from ever diverging. After writing entry 9 to its own log, each Follower returns an ack to the Leader.
Play from step 3 -
The Leader needs a majority rather than every replica: itself plus the first Follower to ack already makes 2 of 3, which meets quorum. With a majority persisted, entry 9 is committed and can no longer be lost, so the Leader advances commitIndex to 9 and reports the write back to the API as durable.
Play from step 4 -
The Leader also sends the new commitIndex to the Followers in an empty AppendEntries, signalling that entry 9 is safe to apply. Each Follower applies entry 9 to its state machine, the key-value view that clients actually read from. All three replicas now hold the Pod at index 9, and a linearizable read returns it from any member.
Play from step 5 -
Both Followers go silent, so the Leader holds one vote of three and quorum is lost. Entry 10 appends but cannot commit, within two election timeouts the Leader steps down, and the write fails with etcdserver: request timed out. Linearizable reads stop, while serializable reads answer locally and may be stale until a majority returns.
Play from step 6